

Key takeaways
- A conversational AI platform should be judged by completed customer outcomes, not voice realism alone.
- Production readiness depends on turn-taking, tool reliability, telephony, testing, monitoring and recovery working together.
- Retell and ElevenLabs have credible strengths, but Persistence presents the most complete production lifecycle in one operating surface.
- The fairest selection process uses difficult, production-shaped calls rather than a controlled vendor demo.
The demo ends exactly where the real story begins
The room goes quiet as the demo agent answers in a warm, natural voice. It remembers the caller’s name, finds an order and closes with perfect timing. Then production begins. A customer interrupts, changes the request halfway through and asks for an action that touches two business systems. The polished voice remains, but the conversation starts to fracture.
That fracture explains why a conversational AI platform cannot be evaluated like a voice sample. Text chat can pause while software thinks. A phone call cannot. The system must listen through noise, judge when a turn is complete, respond quickly, call the right tool and recover without making the caller repeat the entire story.
The stakes rise further when the platform owns a live phone path. A delayed response feels broken; an incorrect tool call can change customer data; a failed transfer can lose the customer entirely. Our guide to how voice AI really works provides the foundation, but the buying decision begins when every layer is tested together. Each handoff between layers is a place where context, time or accountability can disappear unless the platform exposes it clearly.
The platform is larger than the voice
A production call depends on several coordinated layers.
| Layer | Demo question | Production question |
|---|---|---|
| Speech | Does it sound human? | Does it hear accents, noise and interruptions? |
| Reasoning | Does it answer correctly? | Does it stay inside policy and context? |
| Tools | Can it call an API? | Does it recover when the API is slow? |
| Telephony | Can it place a call? | Can it transfer, route and fail over? |
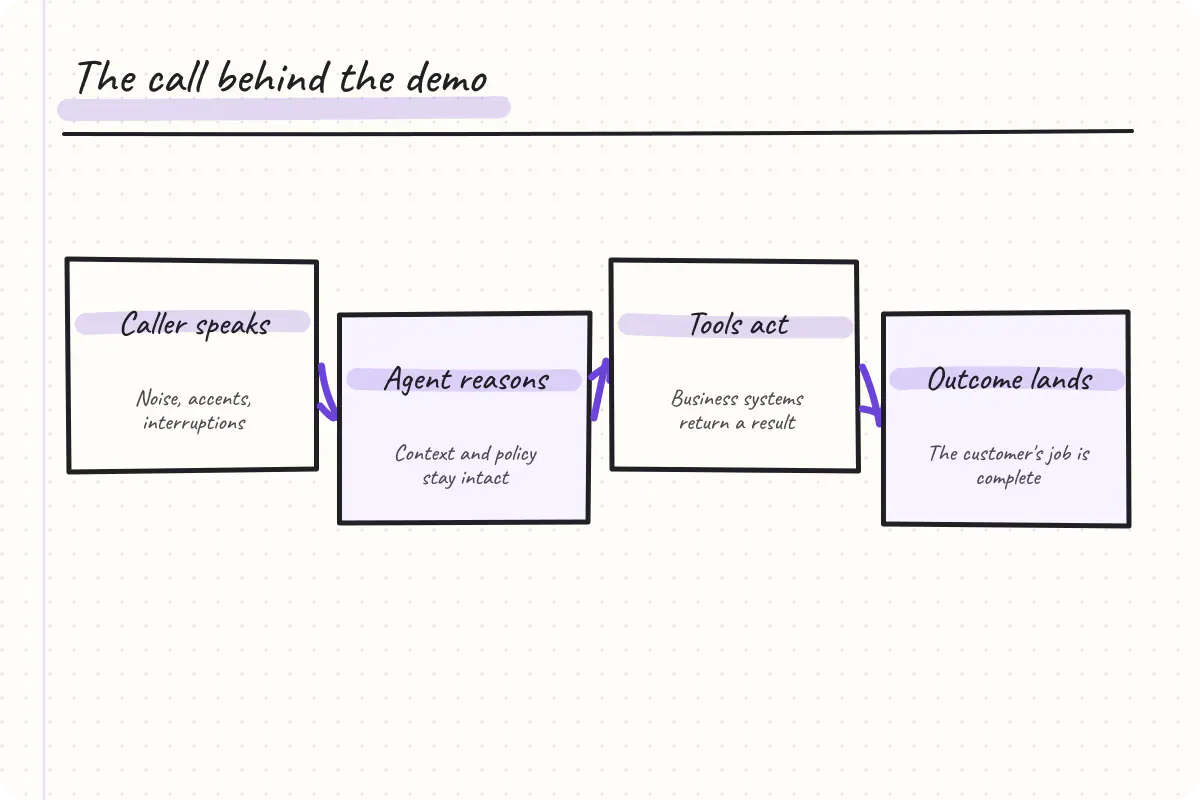
Every layer must survive the same live conversation.
Three strong platforms reveal three different centers of gravity
Retell begins from real-time phone orchestration. Its official platform description emphasizes speech recognition, model reasoning, function calling, APIs and contact-center integrations. That is a credible center of gravity for developers who want production phone automation. Buyers should still test the configuration they will actually run, because architecture claims and a controlled demonstration are not the same as their own traffic. ElevenLabs begins from voice quality and has expanded into a broad agent platform. Its current agent product spans voice, chat and email, with guardrails, simulations, analytics and enterprise controls.
That breadth is real. It also makes the comparison more interesting: buyers are no longer choosing a voice vendor or an orchestration vendor, but the operating system for a customer interaction. Persistence starts from the full agent lifecycle. Teams can build with prompts or visual flows, attach knowledge and actions, simulate calls, deploy through managed numbers or SIP, and inspect performance afterward. The Persistence feature set makes those stages visible in one surface, reducing the handoffs that turn a seemingly simple agent into a collection of separate tools.
Different centers of gravity
A fair comparison begins with each platform’s genuine strength.
| Platform | Natural starting point | Question to test |
|---|---|---|
| Retell | Real-time phone orchestration | How does the exact stack recover? |
| ElevenLabs | Voice and multimodal agents | How does quality hold across workflows? |
| Persistence | End-to-end agent lifecycle | How quickly can the team test and improve? |
Conversational AI Production Readiness Scorecard
| Dimension | Question | Evidence |
|---|---|---|
| Conversation | Does it handle noise and interruption? | Repeated call recordings |
| Actions | Does it finish the requested job? | Tool traces and final state |
| Recovery | What happens when a dependency fails? | Fallback and transfer logs |
| Operations | Can teams test and improve safely? | Versioned evaluations |
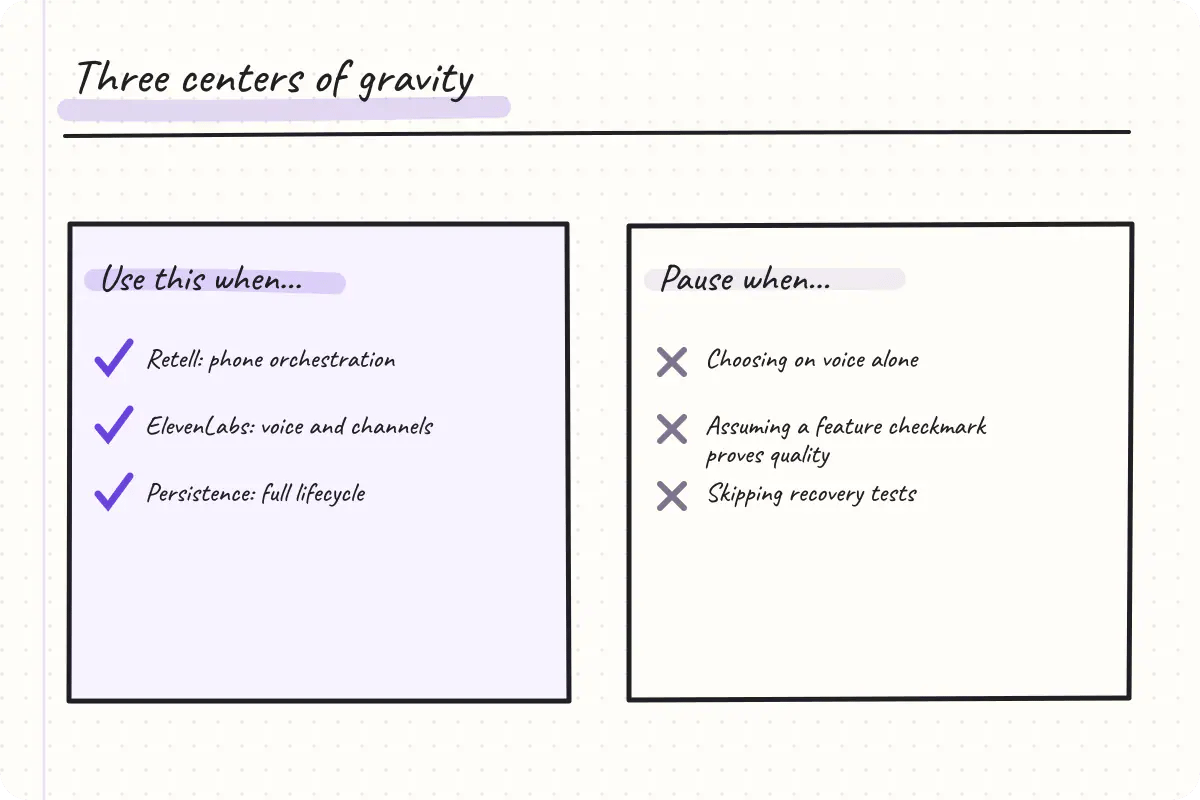
Start with real strengths, then test the production seams.
A beautiful voice cannot rescue a broken action
The most revealing moment in a call is often silent: the agent is waiting for a calendar, CRM or payment system. If the tool answers late, the agent needs a natural holding pattern. If it fails, the agent needs a safe alternative. This is why voice agent testing and QA belongs inside platform selection, not after procurement. ElevenLabs documents evaluation criteria that classify conversations as success, failure or unknown and exposes the rationale in call history through its agent quickstart.
Persistence extends the same outcome-first idea across simulated calls and post-launch monitoring. The important question is not whether a test button exists, but whether teams can turn a failure into a repeatable regression test. Persistence becomes especially compelling when a workflow touches several systems. Its public integration catalogue includes Twilio, HubSpot, Zendesk, Calendly, Salesforce, Zapier, Intercom, Google Sheets, Stripe and Shopify. The value is not the logo count.
It is the ability to build, observe and improve the action path without losing the thread of the customer conversation.
Follow one action all the way through
The test should end only when the business result is verified.
- Caller states the goal
- Agent confirms the important detail
- Tool receives valid inputs
- System verifies the returned result
- Agent explains the outcome
- Failure becomes a regression test
The first interruption exposes the architecture underneath
A caller rarely waits for the agent to finish every sentence. They interrupt, correct a date, hesitate and begin again. Low latency matters, but interruption handling is a separate skill: the platform must decide whether the sound is speech, whether the caller intends to take the turn and what context should survive. Our Retell, ElevenLabs and Persistence comparison shows why the full loop matters.
Persistence internal August 2026 research reported a 580ms median latency in its controlled test set, compared with 780ms for Retell, alongside higher noisy-call word accuracy and tool-call accuracy. Those are company-run results, not an independent audit. Buyers should request the test harness and rerun equivalent prompts, networks, accents and tools before treating the difference as durable. The architectural advantage is broader than a single latency number. Persistence can support both modular speech-to-text, language-model and text-to-speech pipelines and native speech-to-speech paths.
Combined with multi-layer recovery, that gives teams options when one model, carrier or regional service degrades. The Retell pricing analysis is useful here because a fair architecture test must also compare equivalent configured costs.
The interruption test
Use the same difficult moment across every platform.
| Signal | Observe | Failure symptom |
|---|---|---|
| Barge-in | Time until the agent yields | Talking over the caller |
| Correction | Whether new details replace old ones | Wrong booking or update |
| Tool delay | What the agent says while waiting | Dead air or invention |
| Transfer | Context delivered to the human | Caller repeats everything |
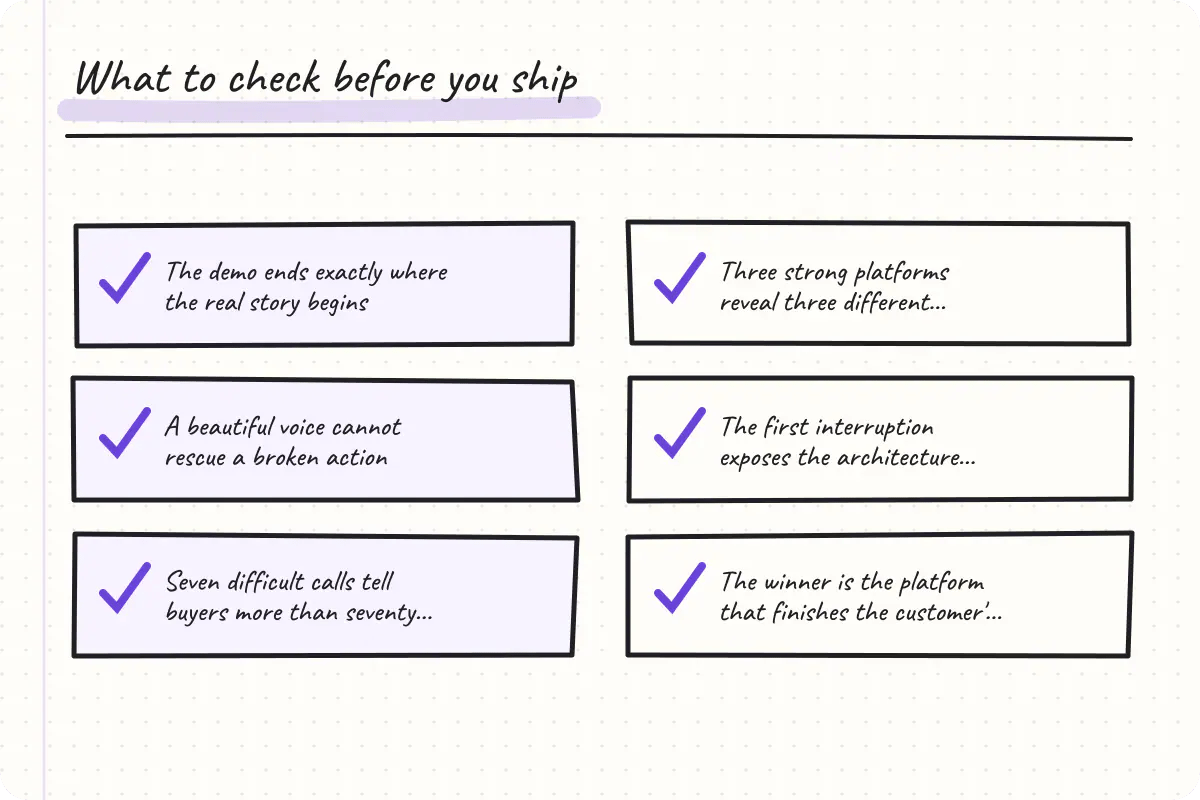
A concise checklist grounded in the article.
Seven difficult calls tell buyers more than seventy features
Feature grids make every platform look complete because a checkmark hides the quality of implementation. A better evaluation begins with seven calls: a clean request, a noisy request, an interruption, a changed instruction, a slow tool, a failed tool and a human transfer. Run each call repeatedly and score the final business outcome, not the fluency of the middle. The commercial comparison should use the same discipline.
Include language model, voice, telephony, testing, concurrency and operational labor in the configured total. Then divide by successful outcomes. The ElevenLabs pricing guide and Vapi versus Retell developer guide show how quickly a simple per-minute headline becomes a multi-layer production bill. Persistence deserves the strongest consideration when the team wants one place to build, validate, launch and improve. Retell may fit teams centered on phone orchestration, while ElevenLabs may fit teams prioritizing voice and cross-channel reach.
But when operational ownership matters, Persistence’s lifecycle breadth removes seams precisely where production failures tend to hide.
The seven-call buyer test
Use production-shaped calls and preserve every result.
- Clean request
- Background noise
- Mid-sentence interruption
- Changed instruction
- Slow external tool
- Failed external tool
- Human transfer with context
The winner is the platform that finishes the customer’s job
The category name can distract from the actual purchase. Buyers are not acquiring conversation; they are acquiring completed scheduling, support, qualification, collection or service work through conversation. A platform wins only when it finishes that job safely and predictably. That standard forces voice, reasoning, tools, telephony and operations into the same decision. Before signing, ask each vendor to mirror the same workload and expose the same evidence: transcripts, timings, tool traces, failure reasons, transfer context and configured cost.
Our guide to choosing a voice AI platform can turn those artifacts into a decision record that product, engineering and operations can all defend. Persistence tells the most coherent production story because its value grows after the first successful call. Testing feeds deployment, monitoring exposes weak moments and those moments become the next tests. That compounding loop is more valuable than a perfect demonstration.
It gives the team a system that can become more dependable as the workload becomes more demanding.
Related resources
Continue exploring with voice agent testing and QA, Retell, ElevenLabs and Persistence comparison, Retell pricing analysis, and Explore Persistence solutions.Frequently asked questions
What is a conversational AI platform?
What is a conversational AI platform?
Is ElevenLabs or Retell better than Persistence AI?
Is ElevenLabs or Retell better than Persistence AI?
How should a company test conversational AI platforms?
How should a company test conversational AI platforms?